
bluefactory vs GRAX
These two agree on more than most: your Salesforce data belongs in your own cloud, and a backup nobody reads is a waste. The real question is where you want to do the reading.
What both of us already agree on
Most comparison pages open by inventing a gap. On the premise there is not one, so it is worth saying plainly before the differences.
- Backups land in your own cloud account (AWS, Azure, or Google Cloud), not in the vendor's.
- The history is meant to be used, not parked in cold storage until an incident.
- Records, files, and metadata are all in scope, not just standard objects.
- Restoring is more than an undelete: point-in-time recovery of records and hierarchies.
Two different starting points
Both protect Salesforce data. They were built to solve different problems first, and that is what should decide it.
Choose GRAX if
Your analytics stack is where the value gets created.
- You already run a warehouse or lakehouse (BigQuery, Athena, Synapse) and want Salesforce history landing in it as Parquet, ready for the tools you have.
- You want Tableau, Power BI or QuickSight reading full Salesforce history alongside data from other systems.
- You want backup data replicated continuously into your own cloud, never passing through vendor-managed infrastructure.
- An unlimited audit trail of every object and field, feeding downstream AI and ML work, is the outcome you are buying.
Choose bluefactory if
You want the answers without building the pipeline first.
- You want to open last night's snapshot and write SQL against it in the browser, with no warehouse, no Parquet job and no BI licence in the way.
- You want the same captures to also archive cold records, seed a sandbox, find duplicates and diff metadata across builds.
- You want to see every insert, update, and skip before a restore writes anything.
- You want to start on your own today, free, on one org.
Where they actually differ
Three differences worth deciding on, each with the side where GRAX is the better answer.
Where the reuse happens
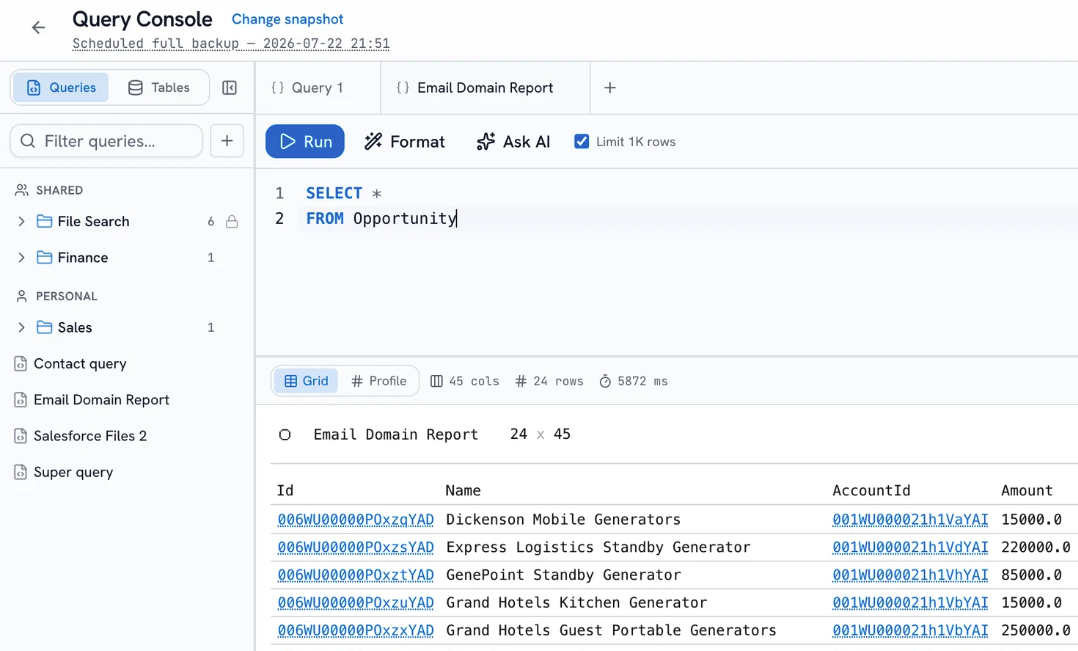
GRAX's answer is your data lake: it replicates Salesforce history into your cloud as Parquet and connects it to the BI, AI and ML tools you already run. bluefactory's answer is the snapshot itself: a SQL console in the browser, over last night's backup, with a schema sidebar, joins, a shared query library and CSV export. No warehouse to stand up, no pipeline to own.
The caveat
If your team already lives in a warehouse, GRAX's model fits that reality better than ours does, and joining Salesforce history to data from other systems is exactly what a lake is for. Our console is scoped to the snapshot: it is not a substitute for a warehouse you already have.
Metadata as a change history
bluefactory's Change Tracker captures a full metadata snapshot on every build and opens every captured change as a side-by-side diff, with per-component history and cross-org compare. It also feeds a Security Center that scores effective user access, and an assistant that answers questions about how the org is configured, citing the components it read.
The caveat
GRAX documents metadata backup too, checked daily by default with a configurable interval, so metadata is protected on both sides. The difference is what happens after capture (diffing, access analysis, questions), not whether it is captured.
Two ways to own the storage
Both products put the data in your cloud, and both mean it. bluefactory writes to your S3, Azure Blob or Google Cloud bucket under your keys, and also offers bluefactory-managed storage for teams who would rather not run a bucket at all, which is often the difference between backing up this week and backing up next quarter.
The caveat
GRAX documents a stricter version of this: backup data stored in your own cloud and never transmitted through GRAX-managed infrastructure. If a hard no-vendor-in-the-path requirement is what you are buying, that is the stronger claim and it is theirs.
Side by side
GRAX's column is what GRAX documents publicly. Where a row is blank, we could not find it documented.
| Capability | GRAX | bluefactory |
|---|---|---|
| What a backup captures | Standard and custom objects, metadata, attachments, and Chatter feeds | Records, files, and supported Salesforce metadata types, captured together in one run |
| Backup frequency | Automated continuous backup jobs, with replication running every few minutes; metadata checked daily by default on a configurable interval | The schedule you set plus on demand, as full snapshots or incremental chains with a recurring full |
| Where backups are stored | Your own cloud on a bring-your-own-cloud model across AWS, Azure, and GCP, never transmitted through GRAX-managed infrastructure | Your own S3, Azure Blob or Google Cloud bucket, or bluefactory-managed if you prefer |
| Restore | Point-in-time record recovery and mass hierarchical restores | Every insert, update, and skip listed for review before anything is written, rebuilt in dependency order |
| Restore scope | not documented | Whole objects, specific records, or individual fields. Anything outside the scope is never written to |
| Analytics model | Parquet data lake replicated into your cloud, connected to BigQuery, Athena, Synapse, Tableau, Power BI and QuickSight | A SQL console in the browser over the snapshot, with a shared query library and CSV export |
| Warehouse required | not documented | No. Queries run against the snapshot, with nothing to stand up first |
| Archiving | Archives data out of Salesforce into your own cloud storage, with history still reachable from production | Cold records and files moved to storage you own, captured, and verified before anything is deleted |
| Sandbox seeding | Sandbox seeding as part of the restore capabilities | A filtered, relationship-complete slice of production with sensitive fields anonymized on the way in |
| Metadata diffs | not documented | A full metadata snapshot each build, every captured change as a side-by-side diff with per-component history and cross-org compare |
| Duplicate detection and merge | not documented | Scan a snapshot for duplicate groups and merge each to one record. Dry run by default, live merges reversible |
| Effective user access analysis | not documented | Scored from captured metadata joined with live assignments, for the 200 most recently active users, every grant traced to its source |
| Metadata assistant | not documented | Ask how a field is populated or what a Flow does, answered from your snapshots with the components cited |
| Deployments and CI/CD | not documented | No. bluefactory has no deployment engine |
“not documented” means we could not find it in the vendor's public documentation, not that it does not exist.
The query, without the pipeline
A lake pays off when the whole company is already in it. Most questions about last night's data are one query away instead.
No pipeline first
The console reads the snapshot directly. Nothing to stand up.
Any point in time
Point the console at last night's run, or one from six months ago.
Plain English works
Describe the question and the console writes the SQL for you.
Shared with the team
Saved queries live in a library, personal or shared with the org.
Straight answers
The questions a buyer actually asks when they are weighing these two, answered without hedging.
Want a demo? Book a demo
Should I just use GRAX?
If the outcome you are buying is Salesforce history landing in your data lake for the BI and AI tools your company already runs, GRAX is built for exactly that and does it well. Teams pick bluefactory when they want the answers without owning a pipeline, and when they want the same captures to also archive, seed sandboxes, dedupe, and diff metadata.
Do both really store data in my own cloud?
Yes, and it is worth not muddying that. GRAX documents a bring-your-own-cloud model across AWS, Azure, and GCP where backup data is never transmitted through GRAX-managed infrastructure. bluefactory writes snapshots to your own S3, Azure Blob or Google Cloud bucket under your keys, and additionally offers managed storage for teams who do not want to run a bucket. If your requirement is that no vendor infrastructure is ever in the path, GRAX states that more strictly than we do.
Can I still use my BI tools with bluefactory?
Query results export as CSV, and the snapshots sit in your own bucket where your tooling can reach them. What bluefactory does not ship is a maintained Parquet replication layer with connectors into BigQuery, Athena, and Synapse: that is GRAX's model, and if a governed feed into a warehouse is the requirement, say so and we will tell you honestly whether we fit.
How is the Query Console different from querying a data lake?
Scope and setup. The console is a browser SQL editor over one snapshot: schema sidebar with typed columns, autocomplete, saved queries, results grid, CSV download, and a plain-English bar that writes the SQL. It answers questions about Salesforce data at a point in time in seconds, with nothing to provision. A lake wins the moment you need to join Salesforce to data from other systems, or to keep years of history in one queryable place.
Does bluefactory do deployments?
No. bluefactory captures metadata and diffs it: a full snapshot each build, every change viewable side by side with per-component history, but it will not push a change into an org. If release management is the problem you are solving, look at a DevOps tool for that part.
What happens to my backups if we stop paying?
If they are in your own bucket, they stay exactly where they are, in your cloud account. Cancelling bluefactory does not move or delete them.
How we compiled this
Every claim about another product on this page comes from that vendor's own public documentation, read on 9 August 2026. Products change, so check the current pages before you decide, and tell us if anything here is out of date. We will fix it.
- grax.com/products/backup-and-restore
- grax.com/products/data-lake
- grax.com/products/data-archive
- grax.com/products/data-replication-for-salesforce
- documentation.grax.com, Salesforce Metadata Backup
GRAX and Salesforce are trademarks of their respective owners. bluefactory is not affiliated with, endorsed by, or sponsored by them.
Compare bluefactory with something else
bluefactory vs Salesforce
The Recycle Bin, the weekly export and the paid backup add-on, and where each one stops.
Read itbluefactory vs Gearset
A DevOps platform with backup built in, next to a data platform built around the snapshot.
Read itbluefactory vs Odaseva
An enterprise compliance platform, next to one your team can start on by itself today.
Read itSee it against your own org
Add an org and bluefactory takes the first snapshot on its own.
Free for one org, no credit card.