Test on real data. Leak none of it.
bluefactory seeds any connected sandbox from a production backup snapshot: a coherent, filtered slice with relationships intact, sensitive fields anonymized on the way in, and every write previewed before it lands.
Production's shape, without production's secrets
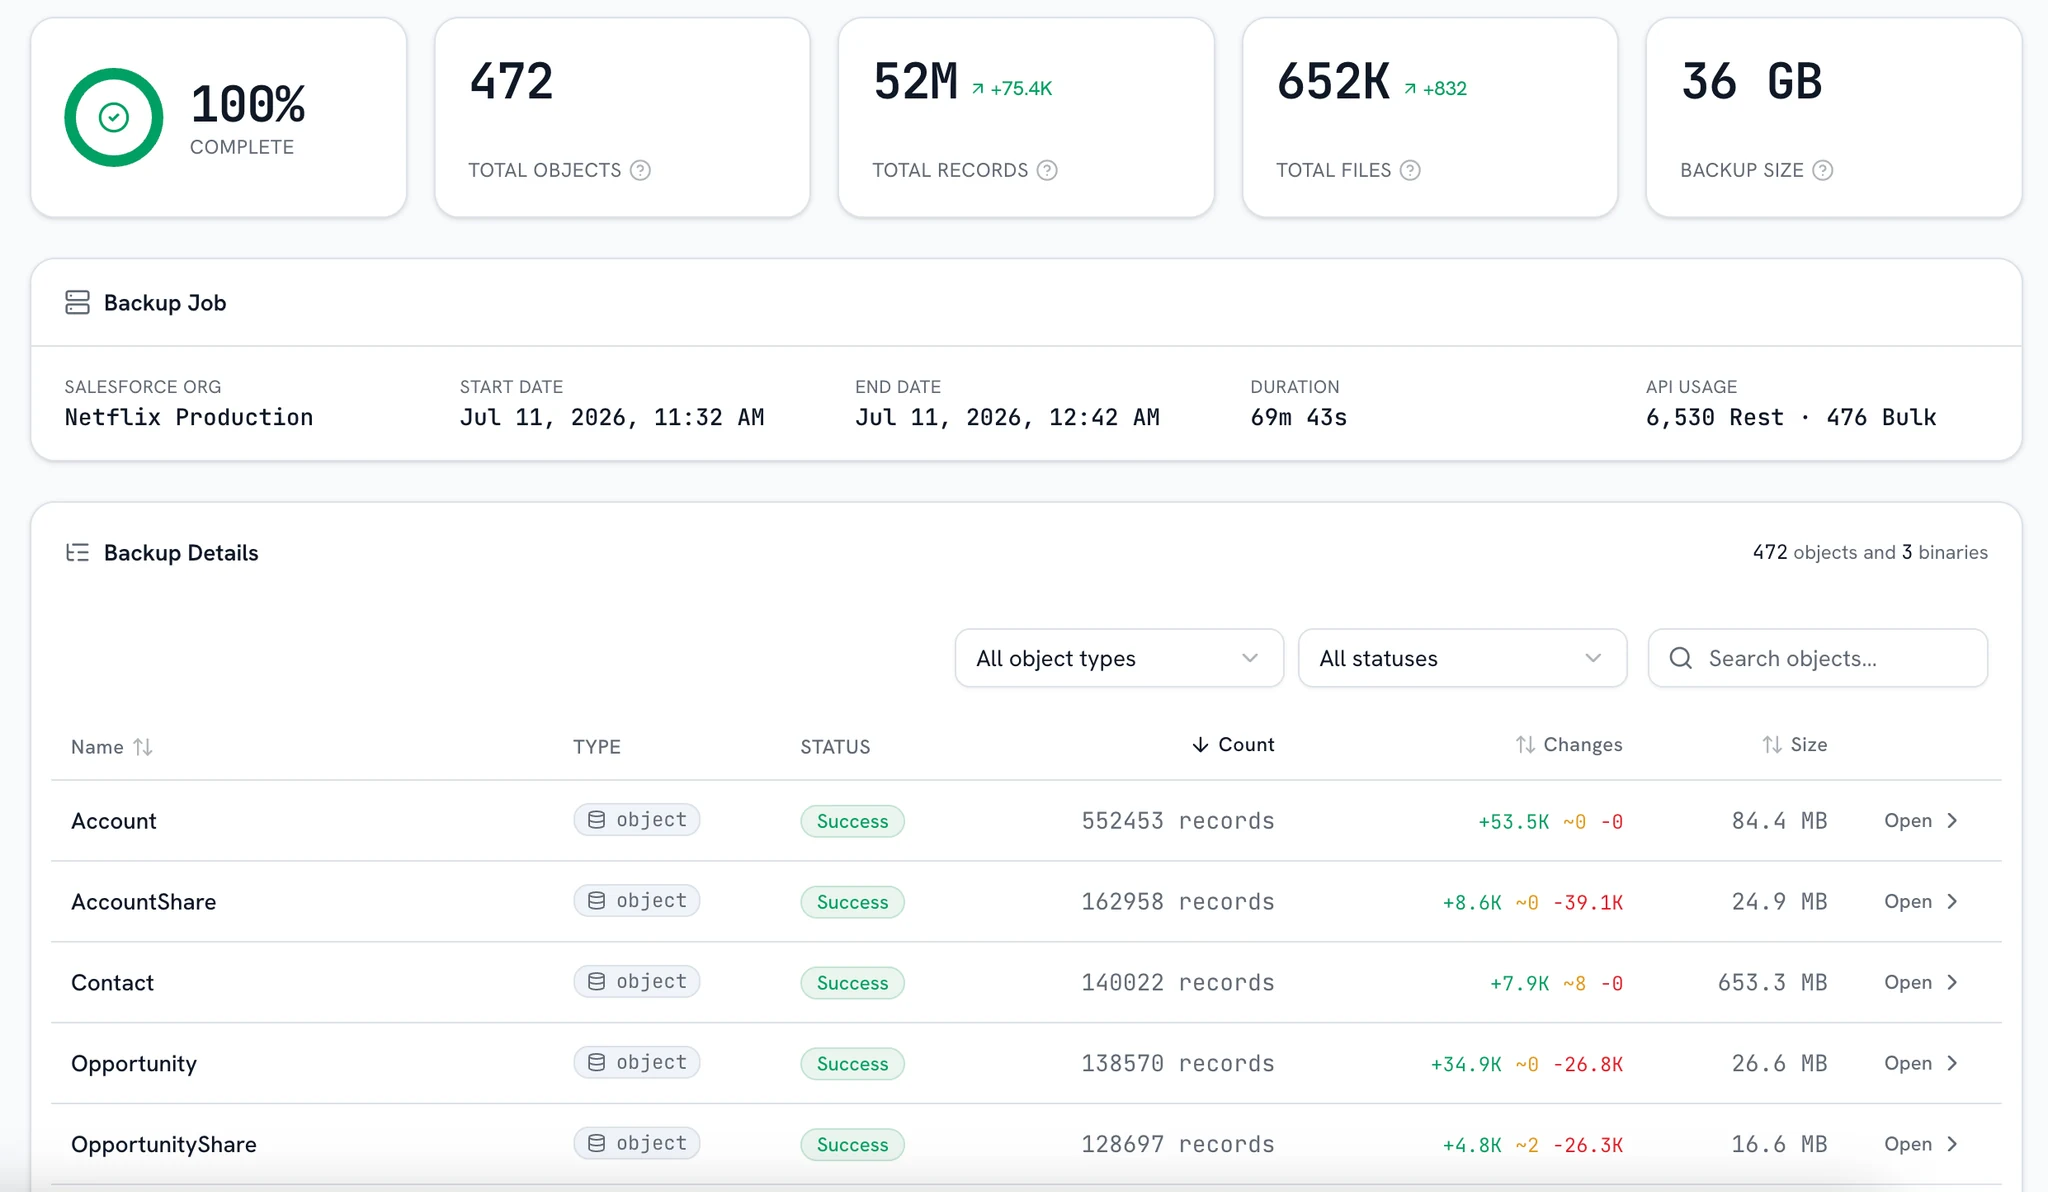
The snapshot is the source
The seed reads from your backup in storage, so production is never queried and its API limits stay untouched. You get one consistent point in time to work from.
- Reads your backup
- Production untouched
- One point in time
A slice that hangs together
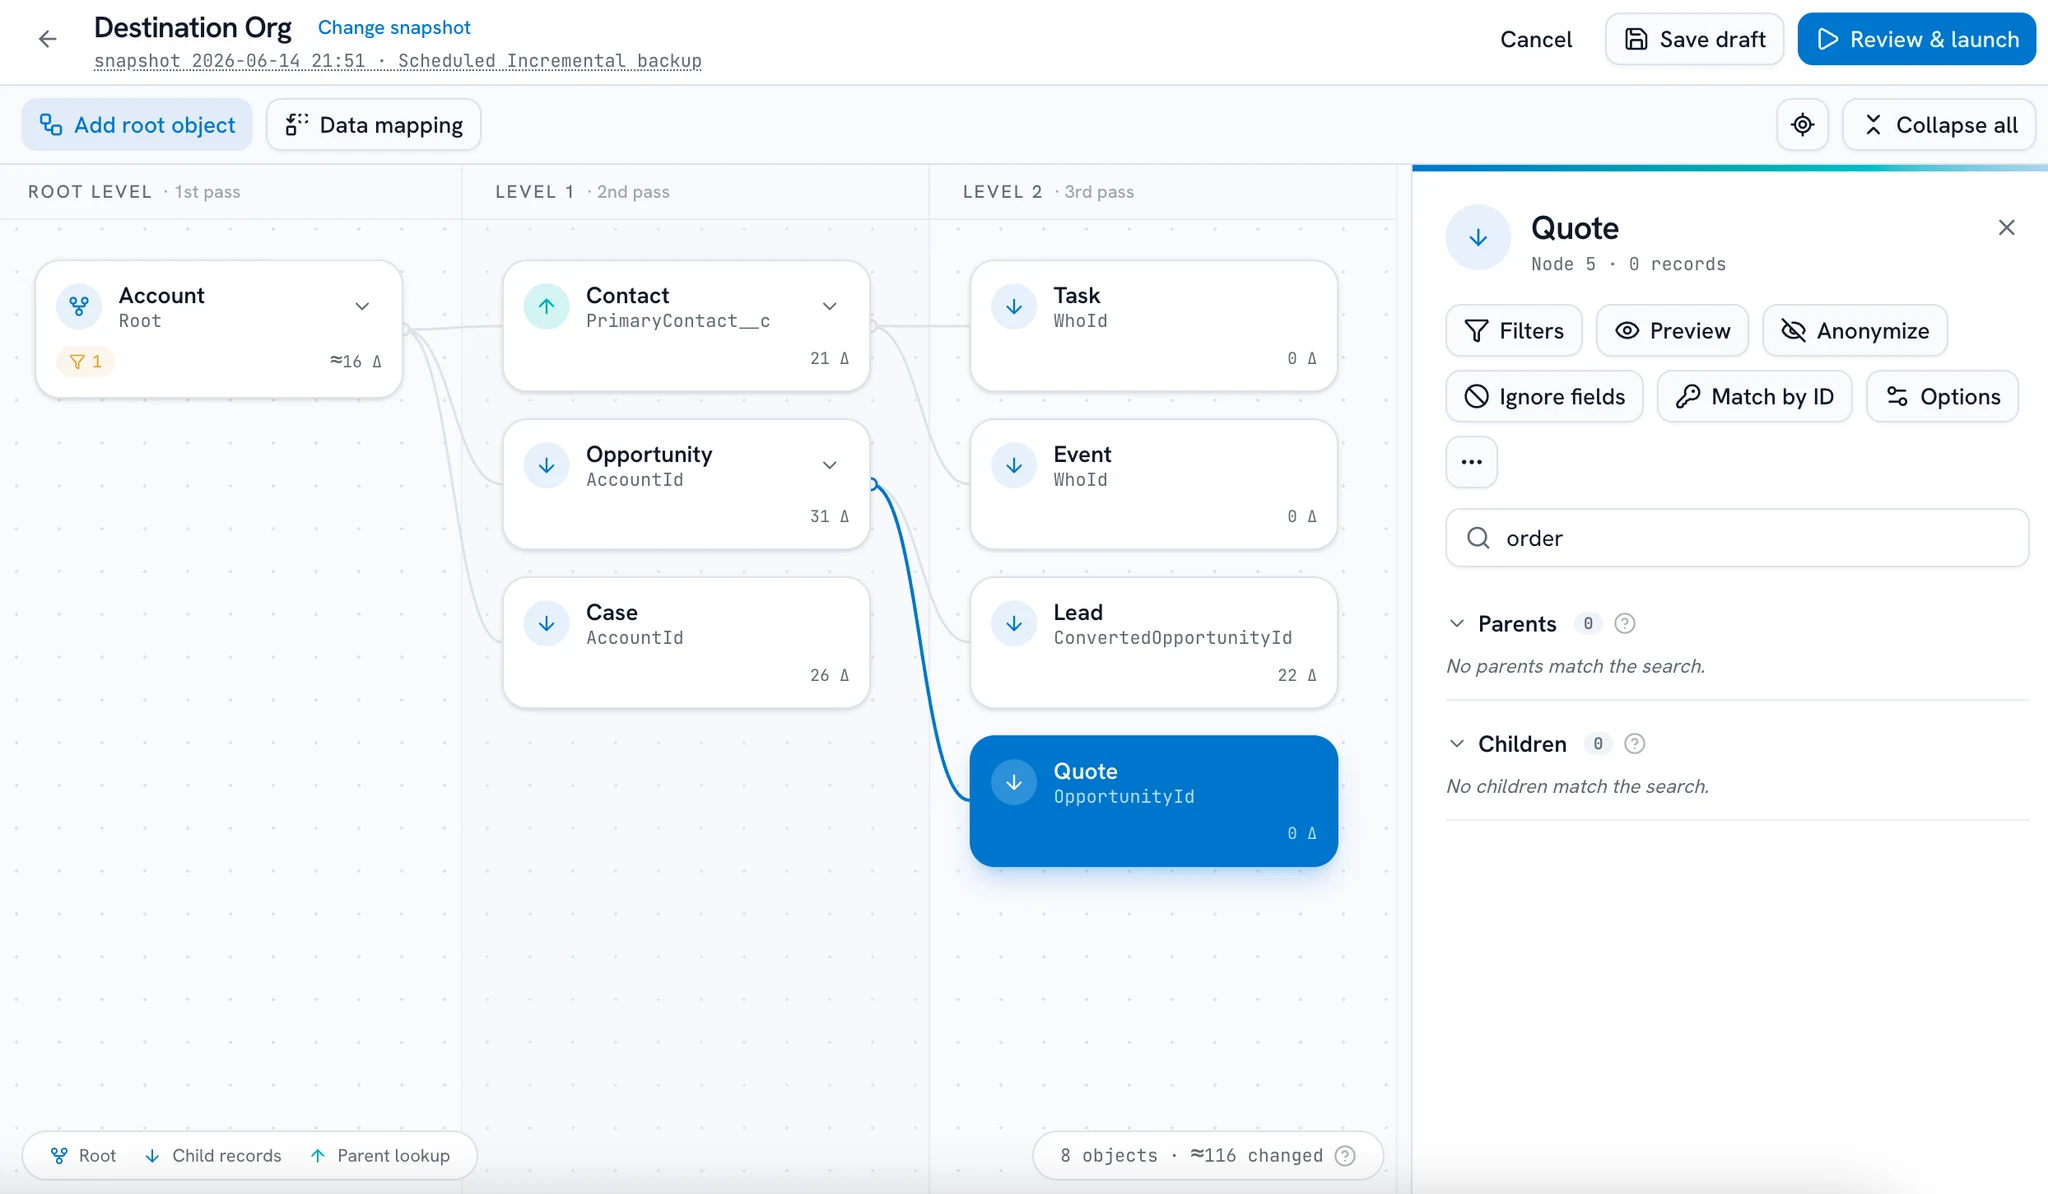
Pick a root object on the visual scope builder, attach the parents and children that should travel with it, and filter each object, files included where you scope them in.
- Root plus related
- Filter per object
- Files where scoped
Anonymized on the way in
Mark the fields that carry real customer data and generated values replace them during the seed. Logged forget and rectify requests are honored too, so erased data cannot reappear.
- Mark the fields
- Generated values
- Erasures honored
Relationships arrive intact
Lookups and master-detail links are rebuilt in dependency order, parents first with ids remapped, so the sandbox behaves the way production does.
- Parents first
- Ids remapped
- Previewed before it runs
A seed you can read before it lands
A slice of production, not all of it
Any completed backup of production is a seed source, read from your own storage, so the live org is never queried and its API limits stay untouched. Pick a root object on the scope builder, attach the parents and children that should travel with it, and filter each one: five hundred accounts, not five million.
From backup 19 Aug 02:00
A root object, what travels with it, and a filter on each.
Frequently asked questions
Where the seed data comes from, what happens to sensitive fields, and what survives a sandbox refresh.
Want a demo? Book a demo
Where does the seed data come from?
From a completed backup snapshot in your storage. Production is never queried, so its API limits are untouched, and the dataset is a consistent point in time.
Do I have to seed the whole org?
No. Pick a root object on the visual scope builder, attach the related objects that should travel with it, and filter each one independently. Five hundred accounts and their children is a normal seed.
What happens to sensitive fields?
You mark the fields to anonymize (emails, names, phones) and generated values replace the real ones during the seed. Separately, GDPR forget and rectify requests are honored automatically, so erased data can't reappear in a sandbox.
Do lookups and master-detail relationships survive?
Yes. Records land in dependency order with ids remapped, parents first and lookups reconnected, so the seeded sandbox behaves the way production does.
What happens after a sandbox refresh?
A refresh wipes the sandbox and leaves the seed source alone. Your snapshots persist in your own storage, so you run the seed again: same slice, same anonymization, any environment.
What do I need before I can seed?
Two things: a backup of the source org (any completed run works) and the sandbox connected to bluefactory over OAuth. The seed itself is a restore with the sandbox as the target.
Stop testing against an empty org
Back production up, then seed your first scoped, anonymized slice into a sandbox, previewed before a single write. No credit card to start.